

Artificial Analysis scores Meta’s Muse Spark Open at 39, behind leading open models
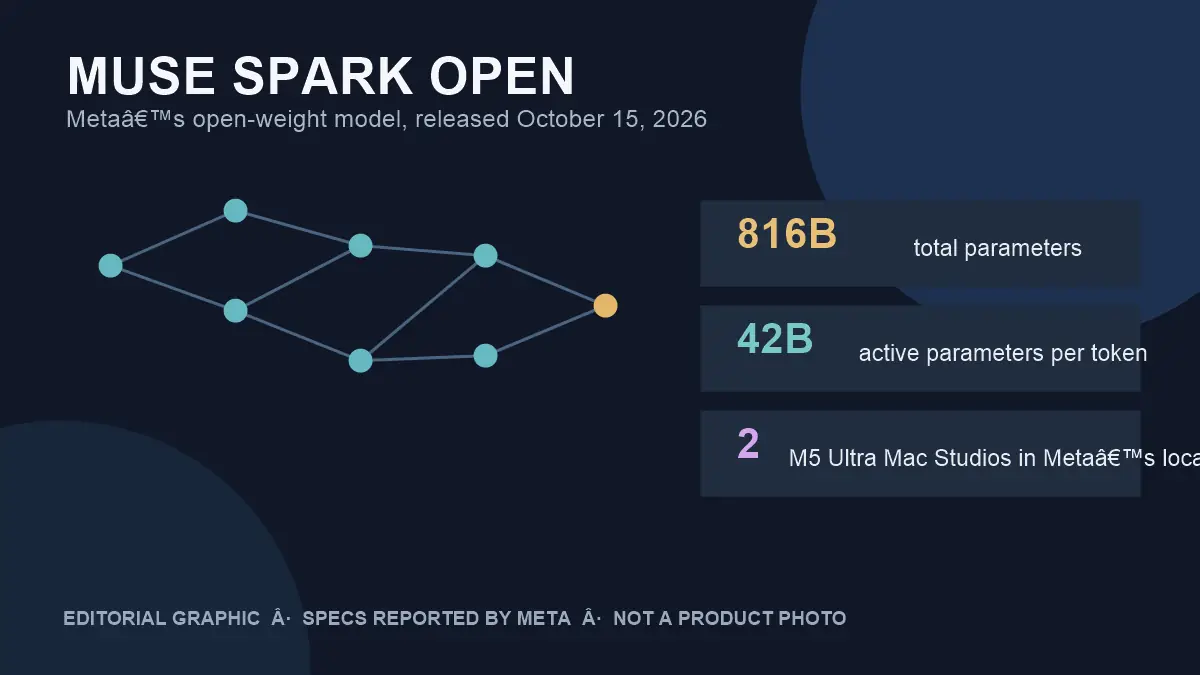 Editorial graphic based on Meta’s published specifications; not a product photo. Meta’s Muse Spark Open has received an independent score on Artificial Analysis’s Intelligence Index: 39 at the Xhigh reasoning setting. The current index lists Xiaomi’s MiMo-V2.6-Pro at 46, Z.ai’s GLM-5.3 (Max) at 45 and Kimi K3 (Max) at 44. That places Muse Spark Open below those open-weight models on this composite, even as Meta’s launch claim was limited to the most capable U.S.-developed open-weight model. [Artificial Analysis’s model results](https://artificialanalysis.ai/models/muse-spark-open) The score combines 10 evaluations covering agentic work, coding, science and general capabilities. Artificial Analysis cautions that its index is a broad comparison and individual tests may matter more for a particular task; the index is primarily text-based and does not measure the model’s image, speech or multilingual capabilities. [Its methodology](https://artificialanalysis.ai/methodology/intelligence-benchmarking) Meta released the downloadable weights on Oct. 15. The company describes Muse Spark Open as a natively multimodal model with 816 billion total parameters, about 42 billion active per token, and a 1-million-token context. It is an open-weight release under a custom license, not an unrestricted open-source license. [Meta’s announcement](https://research.meta.ai/blog/muse-spark-open) Meta’s desktop demonstration used two M5 Ultra Mac Studios, each with up to 512 GB of unified memory; that is the company’s setup, not a confirmed minimum requirement. The Muse Model License also requires model-as-a-service providers with aggregate revenue above $20 million in a rolling 12-month period to notify Meta and enter a separate written agreement. [Model card and license](https://huggingface.co/meta-models/Muse-Spark-Open-816B-A42B/blob/main/LICENSE.md) This benchmark gives readers an independent comparison the launch story did not yet have. It is one composite score, though, and should not be treated as a verdict on every workload. More detailed task-by-task and multimodal comparisons will show where the model is strongest. This is a different release from the Muse Wonder models covered [earlier](https://www.mushimu.com/post/8960). ~ai